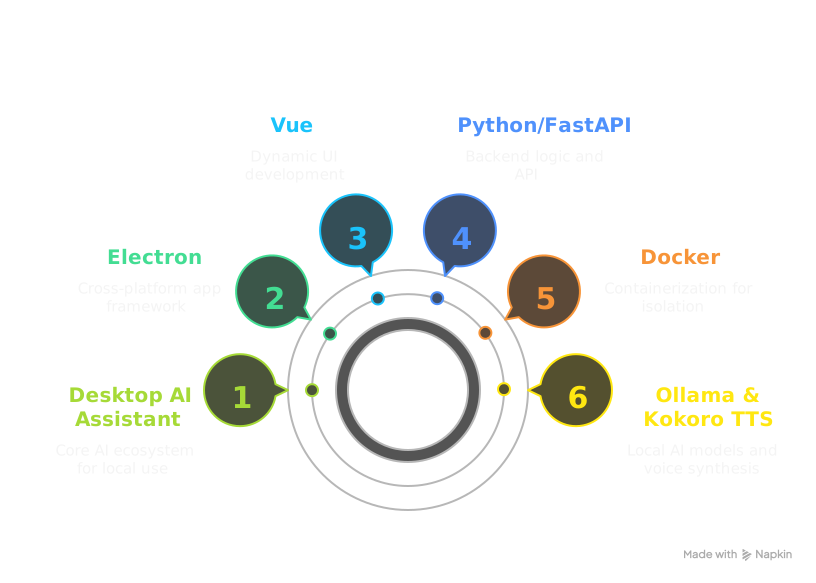
The tech stack behind our desktop AI assistant
Our desktop AI assistant combines Electron, Vue 3, FastAPI, Docker, Ollama and Kokoro TTS, with local models for privacy. Electron's main process handles operating system access, and FastAPI runs the Python AI services.
The Desktop AI Assistant combines local AI models, an Electron shell and FastAPI services in one app. In a previous post, we showed that Google Gemini 2.5 Pro Preview generated 100% of its code. This post covers the technology, the features and how the parts connect.
We needed a stack that handled the user interface, real-time AI interaction, backend processing and resource-heavy tasks in isolation. It also had to bring AI models to the user's desktop, with local processing for privacy and control.
Core technology stack
Several key technologies make up the foundation. Gemini coded each of them.
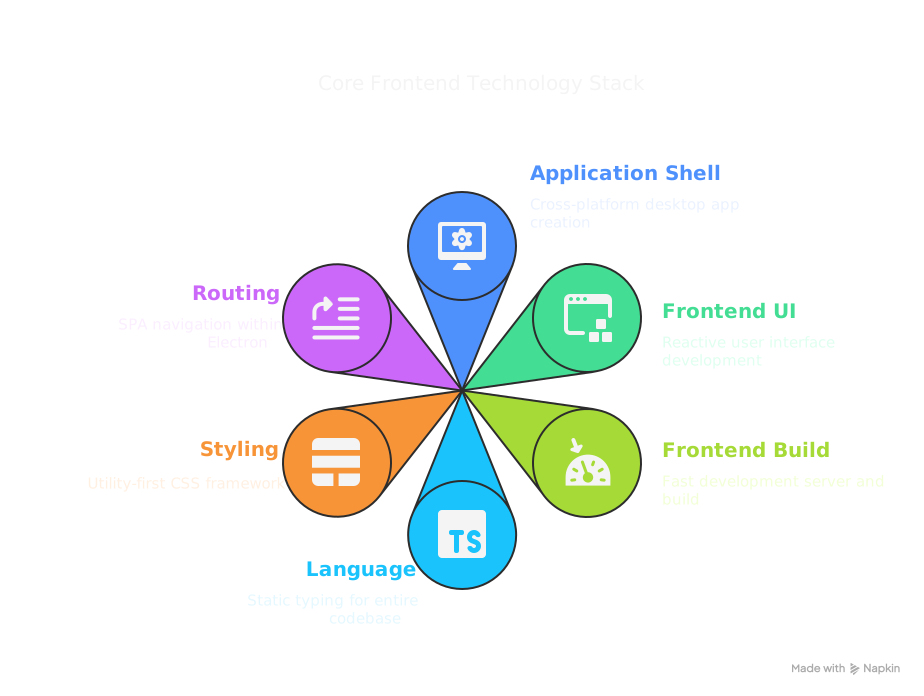
Desktop application shell and UI
| Category | Technology/Tool | Role & Purpose |
|---|---|---|
| Shell | Electron (with Electron Forge) | Cross-platform desktop app creation and packaging. |
| Frontend UI | Vue 3 (Composition API, Composables) | Reactive user interface development for multi-modal interactions. |
| Frontend build | Vite | Development server and build tool for Vue. |
| Language | TypeScript | Static typing for the entire codebase. |
| Styling | Tailwind CSS | Utility-first CSS framework. |
| Routing | Vue Router | SPA navigation within Electron. |
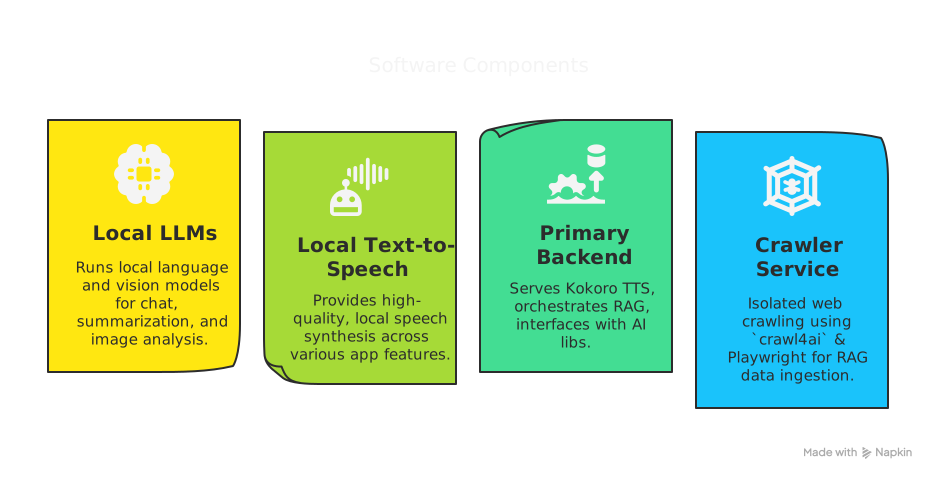
Local AI and backend services
| Category | Technology/Tool | Role & Purpose |
|---|---|---|
| Local LLMs (Text & Vision) | Ollama Server (External) | Runs local language and vision models for chat, summarization and image analysis. |
| Local text-to-speech | Kokoro TTS (via FastAPI) | Provides high-quality local speech synthesis across app features. |
| Primary backend | Python, FastAPI, Uvicorn | Serves Kokoro TTS, orchestrates RAG and interfaces with AI libraries. |
| Crawler service | Docker, Python, FastAPI (minimal) | Isolated web crawling with crawl4ai and Playwright for RAG data ingestion. |
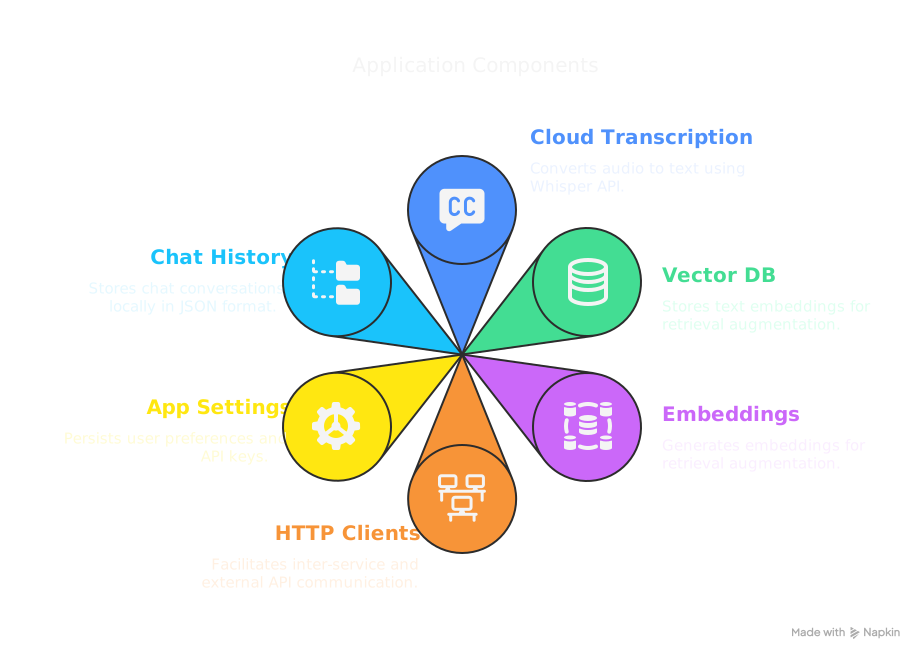
Cloud AI, data handling, communication and storage
| Category | Technology/Tool | Role & Purpose |
|---|---|---|
| Cloud transcription | OpenAI Whisper API (External) | Audio-to-text conversion (user-provided API key). |
| Vector DB (RAG) | ChromaDB | Stores text embeddings for RAG. |
| Embeddings (RAG) | Sentence Transformers | Generates embeddings for RAG. |
| HTTP clients | Axios (Electron), HTTPX (FastAPI), Node HTTP | Inter-service and external API communication. |
| App settings | electron-store | Persists user preferences for API keys and default models. |
| Chat history | Local filesystem (JSON) | Stores chat conversations locally. |
Core features
The stack supports these features:
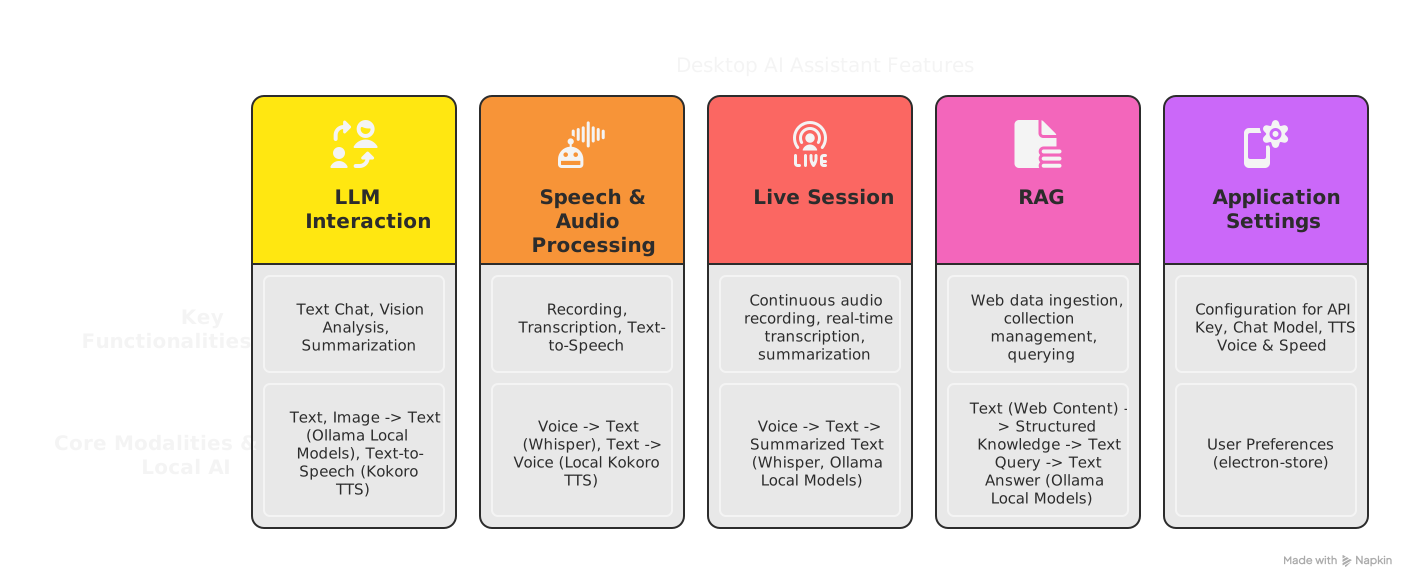
| Feature area | Key functionalities | Core modalities and local AI |
|---|---|---|
| LLM interaction |
Text chat: streaming, model selection, system
prompt, history. Vision analysis: image upload or URL, text prompts for image queries, model status, explicit loading. Summarization: for transcripts and live sessions. |
Text, Image -> Text (Ollama local models), Text-to-Speech (Kokoro TTS for responses) |
| Speech and audio processing |
Recording: one-off and continuous segmented.
Transcription: OpenAI Whisper for speech-to-text. Text-to-speech: Kokoro TTS for speaking assistant messages, vision descriptions and dedicated TTS testing. Voice and speed selection. |
Voice -> Text (Whisper), Text -> Voice (local Kokoro TTS via FastAPI) |
| Live session | Continuous audio recording, real-time Whisper transcription, progressive Ollama re-summarization of the full transcript, live UI updates, performance stats. Session persistence and AI-generated titles. | Voice -> Text -> Summarized Text (Whisper, Ollama local models) |
| Retrieval-augmented generation (RAG) | Web data ingestion (via Dockerized crawl4ai), collection management, chunking, embedding (Sentence Transformers), ChromaDB storage, natural language querying against custom knowledge, and display of contextual answers and retrieved sources. | Text (web content) -> Structured knowledge -> Text query -> Text answer (Ollama local models for RAG answers) |
| Application settings | Configuration for OpenAI API key, default Ollama chat model, default Kokoro TTS voice and speed. | User preferences (electron-store) |
Local Kokoro TTS runs across the app. The assistant can voice an LLM chat response or a vision model's description of an image, which makes interactions more natural and accessible. Local Ollama vision models analyze images on the user's machine, which fits our local-first design.
Key integrations and architectural patterns
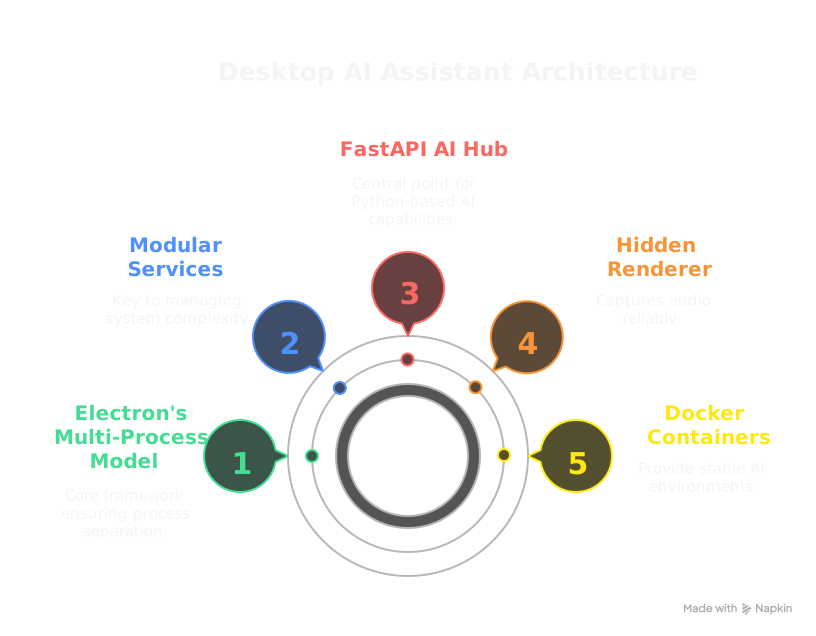
The architecture connects these technologies in five ways:
- Electron's multi-process model separates the UI (renderer) from backend tasks and native interactions (main process). Secure IPC through contextBridge connects them.
- Modular services run through the whole app, from Electron's main process services and preload APIs to FastAPI's routers and the rag_core business logic. Modularity was a core instruction to Gemini, and it was key to managing the system.
- FastAPI is the Python AI hub. It exposes Kokoro TTS as an API and orchestrates the RAG pipeline, including the Dockerized crawler. Heavy Python dependencies stay out of Electron's main process.
- A hidden renderer captures audio with standard Web APIs. That audio feeds Whisper transcription and possible future local audio processing.
- Docker keeps the crawler stable. The crawl4ai and Playwright setup is critical for RAG data ingestion, and it runs in a predictable container, which avoids platform-specific problems.
Local computer control and automation
The main advantage of a desktop AI assistant is that it can interact with the user's local computer. Web-based cloud apps cannot do this because of browser sandboxing and security restrictions.
Electron's main process can call Node.js APIs, which reach the operating system, the file system and other local applications. A local LLM that understands natural language and generates structured output, such as scripts or command sequences, makes many tasks possible:
- For automated tasks, a user could say: "Organize all my screenshots from the last week into a new folder named 'May Week 3 Shots' and then open that folder." The assistant parses the request, uses Electron's main process to work with the file system and runs the commands.
- For application control, a user could say: "Open my code editor, launch the 'PM Desktop App' project, and start the development server." This is complex, but an LLM could generate the shell commands, and Electron's main process could run them.
- A locally controlled headless browser could handle tasks that need browser interaction but are not web scraping. Playwright, run by Electron's main process or a local utility script, could work with local network devices that have web UIs, or with internal company portals that are not public. The Dockerized crawler shows what headless browsers can do, and bringing that control local and secure opens new options.
- For content and files, a user could say: "Draft an email to John about our meeting, save it as 'meeting_notes.txt' in my Documents, and then open it for review." The LLM writes the text, and Electron creates and opens the file.
Security comes first. Electron separates the renderer (UI) from the main process (Node.js and OS access), and that separation is the basis for this work. Local control features need careful design:
- All OS-level interactions happen only in the Electron main process.
- The sandboxed renderer (Vue UI) sends high-level, validated commands to the main process over IPC.
- The main process sanitizes and runs these commands, possibly with user confirmation for sensitive actions.
- Local LLMs (Ollama) handle the intent understanding too, so the core control logic has fewer external dependencies.
This deeper integration with the local computer, powered by private local LLMs, is a step toward a personal AI assistant that understands your context from your own machine, not only from the web.